SPLIT reconstructs a 3D scene from video and gives a vision-language model tools to query it. Tested
with Gemini 3.1 Pro, GPT-5.5, and Claude Opus 4.8, it reaches 66.9% accuracy on VSIBench, 78.3% on
VSTIBench, and 71.5% on ReVSI without additional training. Supplying ground-truth measurements raises
accuracy to 96.7%, showing how much errors in perception affect the results.
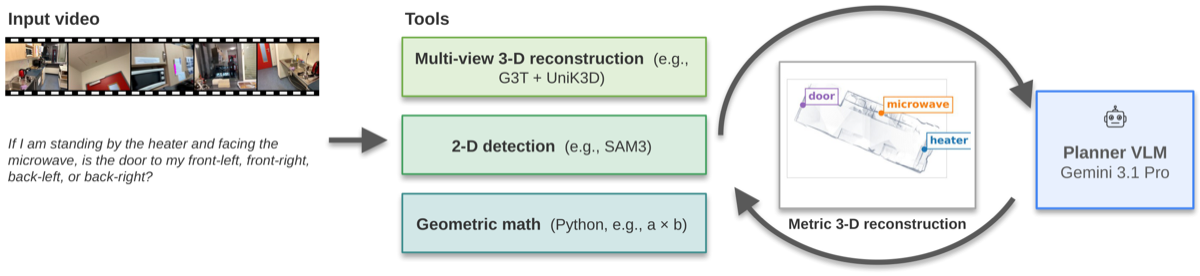
We introduce SPLIT, a training-free harness that reconstructs one metric 3-D point cloud from a video
and gives a planner VLM tools to query it. Frozen reconstruction and grounding models locate objects and
measure their geometry, and the planner VLM combines those measurements using Python. SPLIT improves
accuracy on VSIBench, VSTIBench, and ReVSI, achieving the best published training-free score on
VSIBench. On VSTIBench, it raises accuracy from 57.7% to 78.3%, eliminating 49% of the baseline VLM's
errors. Rerunning SPLIT with ground-truth measurements in place of the tools' estimates shows that
inaccurate perception, not reasoning, remains a major source of error.
@misc{yeung2026split,
  title = {Perception, Not Reasoning, Limits Video Spatial Understanding},
  author = {Yeung, Jacob and Goyal, Mohit and Dubost, Florian and Vondran Jr., Gary L. and Tombari, Federico and Ramanan, Deva and Tarr, Michael J.},
  year = {2026}
}